Sitemap
A list of all the posts and pages found on the site. For you robots out there, there is an XML version available for digesting as well.
Pages
projects
RL for Robot Navigation
Individual Project, Human-Centered Robotics (CSCI 573)
Coded on-policy and off-policy reinforcement learning algorithms from scratch for robot navigation by following a wall using LiDAR data. Implemented in ROS and Python, using Gazebo for simulation.
Bidirectional Communication for Disambiguating Mobile Manipulation Requests
Group Project, Mobile Manipulation (ROB 762)
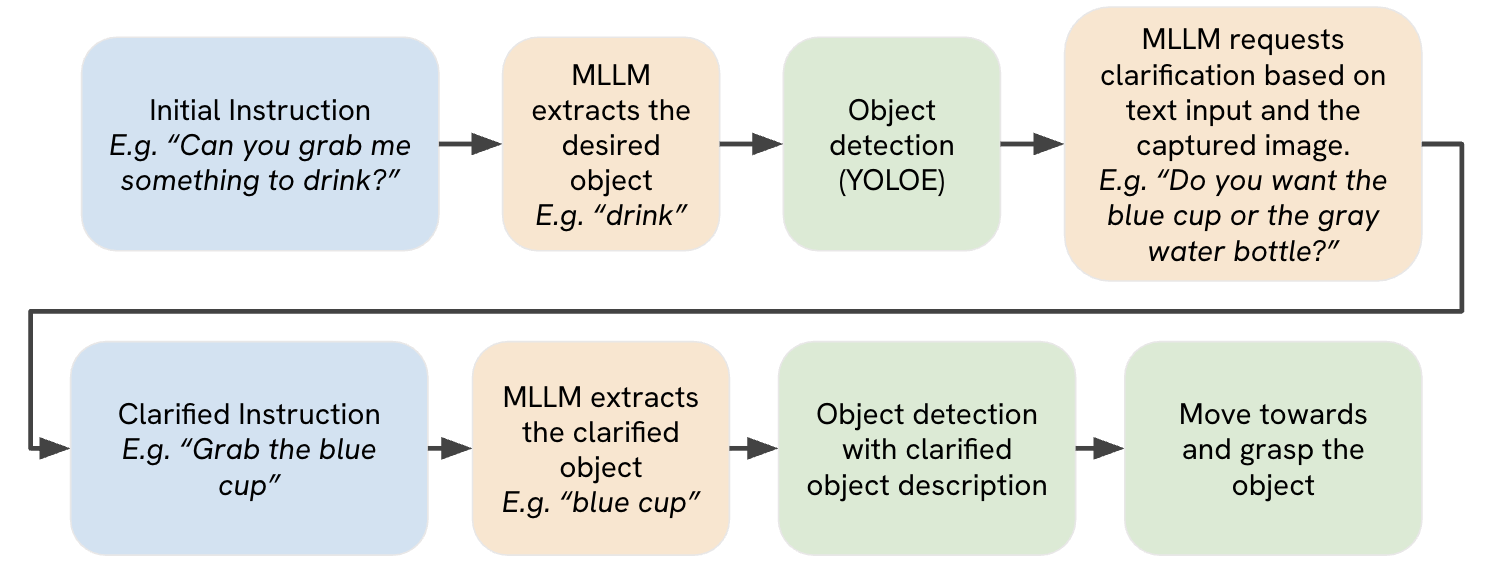
Designed a bidirectional communication system to resolve ambiguous fetch and return tasks. Used VLMs to determine whether a request is ambiguous based on the current scene and request more information if it is. Implemented object detection and mobile pick and place on a Stretch 3 mobile robot.
Evaluated our pipeline with tasks related to grabbing a drink as well as more general tasks that had a variety of objects. Clarification was correctly requested 100% of the time for the drink tasks but only 20% of the time on general tasks. This demonstrates the potential for out-of-the-box VLMs to clarify requests in simple tasks, but this can fail in more complex and ambiguous scenarios.
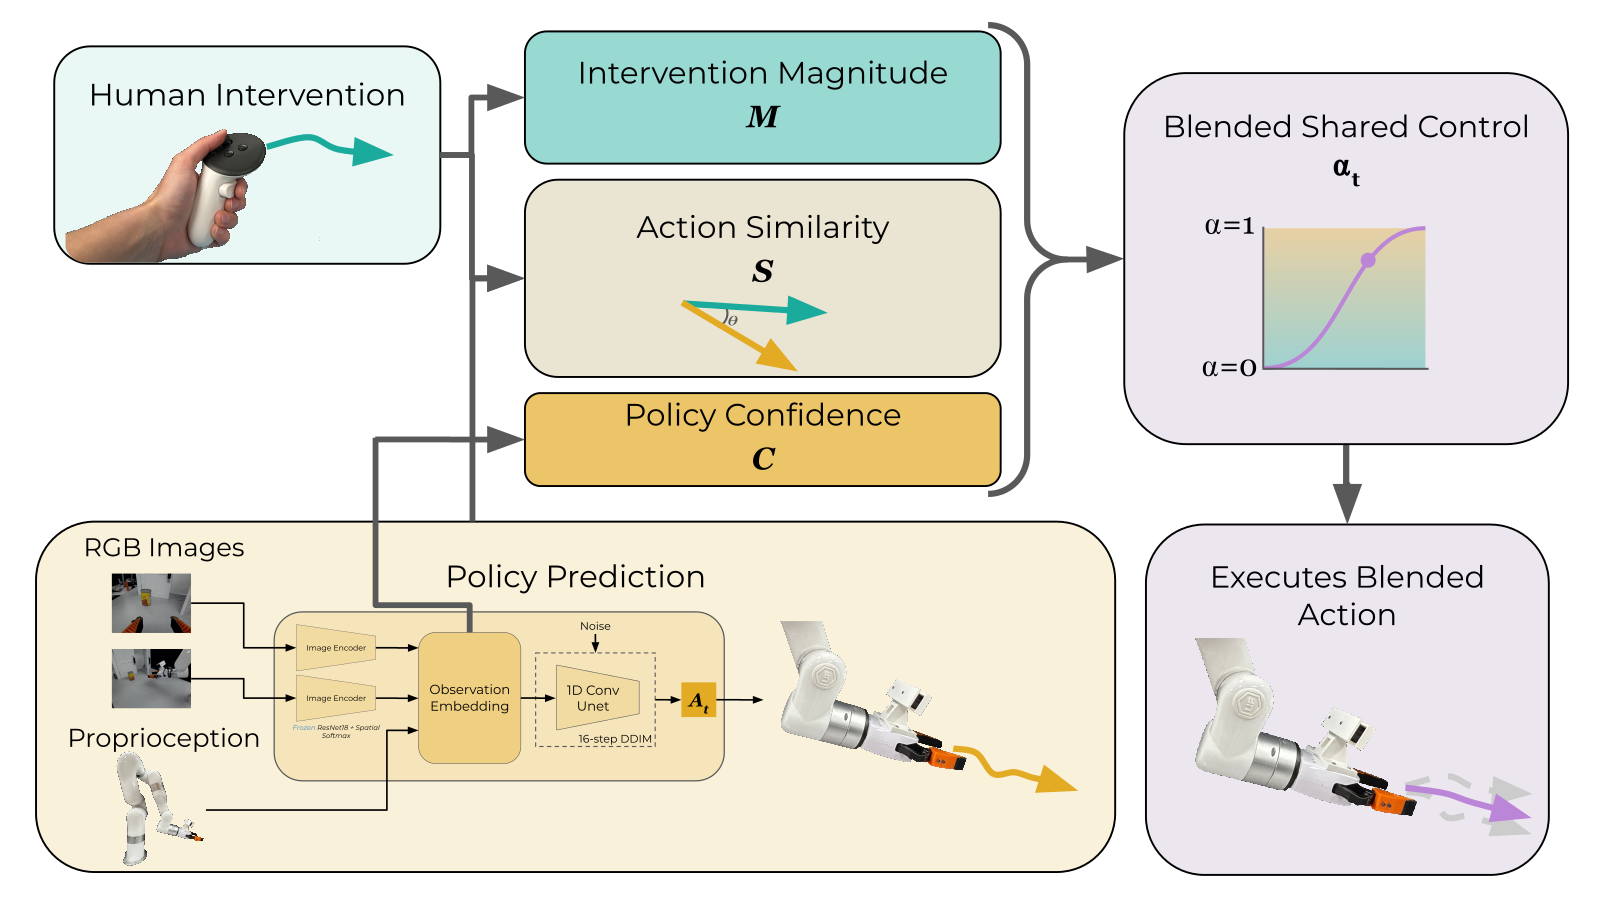
Blended Shared Control for Interactive Imitation Learning
Research Project, in Submission as First Author
Novel approach for collecting data to fine-tune imitation learning policies using blended shared control during interventions for better autonomous performance. In comparison to full human control during interventions (HG-DAgger), our approach results in:
- Higher autonomous performance by over 30 percentage points on two long horizon real-world tasks
- ~15% faster data collection
- 40% smoother transitions from autonomous rollouts to human interventions and 63% smoother transitions from interventions to rollouts
Object Grasping with RL
Group Project, Robot Learning (ROB 831)
Implemented and compared on-policy (PPO), off-policy (SAC), and model-based (MBPO) on object grasping in the RoboSuite simulation. Compared policy performance on vision-based and state-based inputs and with warmstarting from imitation learning. See more details here.